Architecting High-Scalability Lakehouses for Retail Forecasting: Moving Beyond Legacy Tooling
Learn how v4c modernized retail forecasting with a governed Databricks lakehouse, migrating from legacy tooling to scalable ingestion, quality, governance, and analytics.

The Industry Challenge
Modern consumer goods and retail corporations depend heavily on constantly evolving data streams. These include financial planning instruments, supply chain inputs, production systems, and demand signals, all of which arrive from diverse platforms in varying formats as a continuous stream. Yet for most organizations, that data still lives in silos. ERP systems, cloud data stores, and specialized analytics platforms operate independently, and the pipelines connecting them are often brittle, hand-built, and tightly coupled to whatever tooling was in place when they were written. This fragmentation has real consequences. Forecasting models are only as good as the data feeding them, and when ingestion, transformation, and quality checks aren't standardized, inconsistencies creep into every downstream report. Teams end up reconciling numbers instead of acting on them. Governance suffers without a common access-control and lineage layer, and enforcing consistent data policies across business units becomes a manual, error-prone exercise.
Legacy platforms, and proprietary analytics stacks like Palantir, compound the problem. They're expensive to run, difficult to extend, and architectured around their own ecosystems rather than open standards. For a retail or manufacturing organization trying to scale toward AI-driven demand forecasting, that combination of cost, rigidity, and fragmentation is a structural ceiling, not a temporary inconvenience.
The Architectural Blueprint
The solution requires a fundamental transition to a governed lakehouse architecture. As a leading Databricks consulting partner, v4c.ai has developed a steady, repeatable implementation pattern for making this transition on the Databricks Data Intelligence Platform.
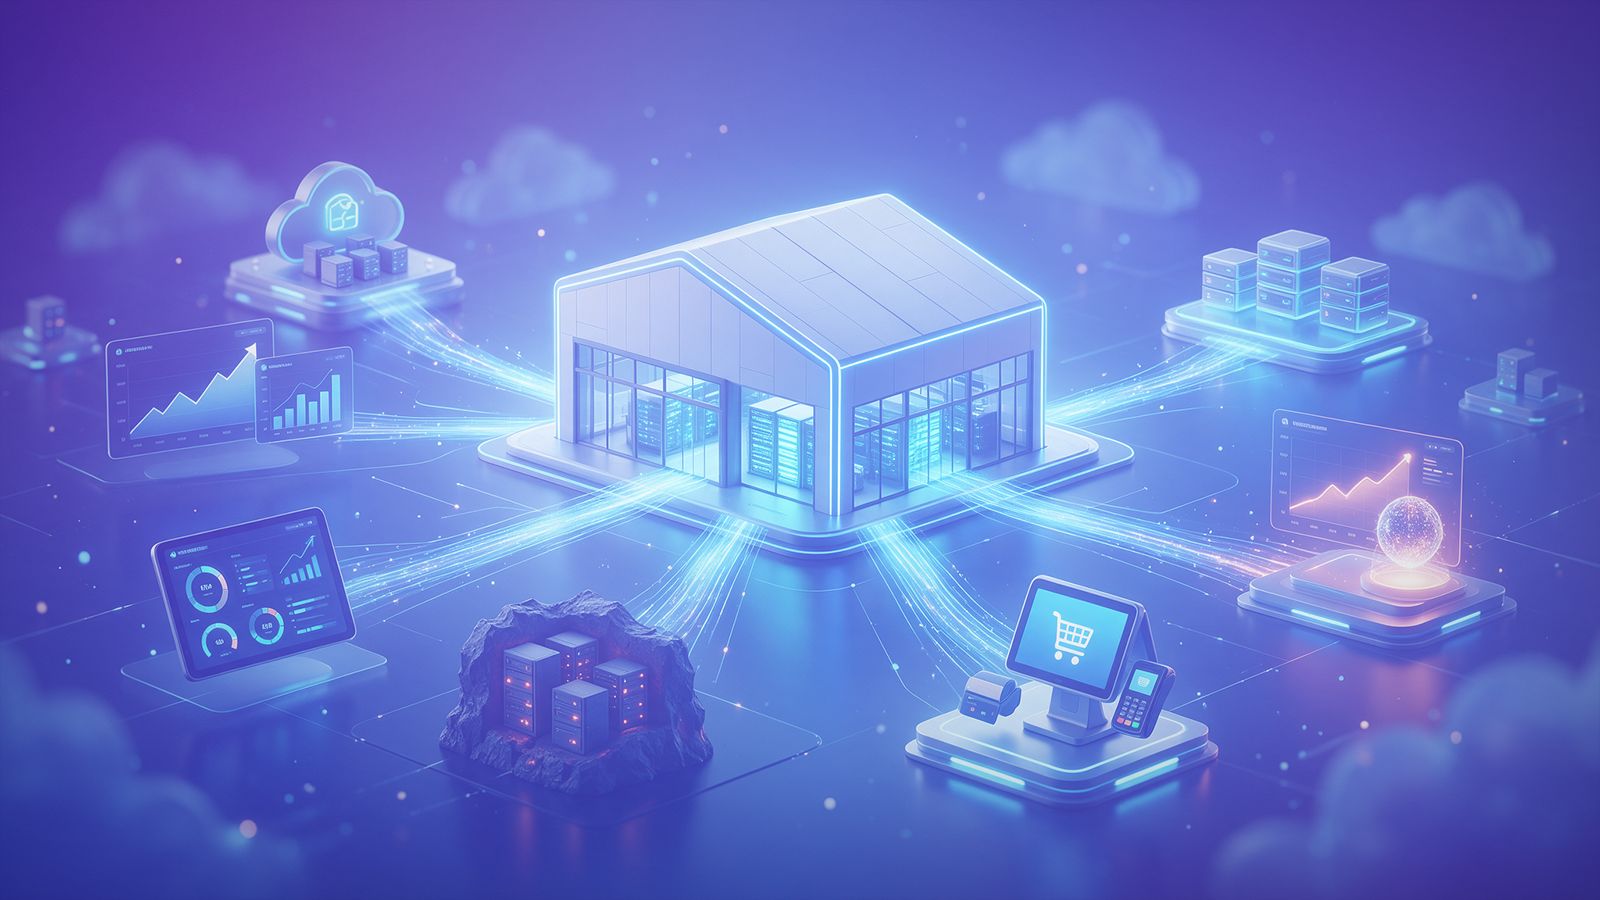
Ingestion: v4c builds custom Python and Spark-based extraction frameworks that pull data from enterprise systems, SAP, cloud-native sources, and beyond into a centralized lakehouse. Building these as modular, reusable components (rather than one-off scripts) means each new data source can be onboarded without re-architecting the pipeline layer.
Transformation and quality: v4c structures data using a medallion architecture (Bronze, Silver, Gold), organizing it by level of refinement: raw ingestion, validated and cleaned data, and business-ready datasets. Using Delta Live Tables (DLT), v4c standardizes this transformation logic and embeds data quality checks directly into the pipeline, so validation isn't a separate audit step, it's built into how data moves.
Migration: v4c leads the migration of workloads off Palantir, re-engineering pipelines and optimizing data models rather than simply lifting and shifting. Done correctly, this consolidates the data stack into one environment on Databricks and removes the dependency on costly, closed tooling.
Governance and deployment: v4c stands up Unity Catalog as the centralized layer for access control, lineage tracking, and policy enforcement across every dataset in the platform, alongside CI/CD processes that ensure pipeline and infrastructure changes are deployed consistently, turning what used to be manual, risky releases into repeatable ones.
Operational & Business Outcomes
Organizations that make this shift see the benefits in three places.
- Cost transparency improves as fragmented, license-heavy legacy systems are retired in favor of a single consolidated platform.
- Data trust improves, standardized pipelines and embedded quality checks mean the numbers feeding forecasting and financial planning are consistent by design, not by manual reconciliation.
- Development velocity increases, as modular ingestion frameworks and automated deployments reduce the engineering effort required to onboard new sources or extend the platform.
By consolidating more than 10 disparate data sources into a single governed environment, v4c built a unified lakehouse for a partner RCT organization on the Databricks platform, laying the foundation for demand forecasting and financial planning applications that simply weren't feasible on the prior architecture.
Strategic Key Takeaway
Treat migration as re-architecture, not lift-and-shift: Moving off legacy platforms is the moment to fix data model and pipeline design flaws, not just relocate them.
Bake quality into the pipeline, not around it: Embedding validation into DLT transformation logic scales far better than bolting on checks after the fact.
Govern from day one: Standing up Unity Catalog alongside, not after the ingestion layer keeps access control and lineage from becoming technical debt.
More blog posts